Nvidia swept all seven MLPerf Training tests with Vera Rubin, running 2x faster per GPU
Nvidia swept all 7 MLPerf Training tests on November 16 with Vera Rubin, up to 2x faster per GPU than the GB300 system it replaces.
The decision it puts on your desk
Re-price your 2027 compute budget within 7 days, using power as the unit. Lock orders by January 31.
Nvidia swept all seven MLPerf Training tests on November 16, with Vera Rubin running up to 2x faster per GPU.
Training results
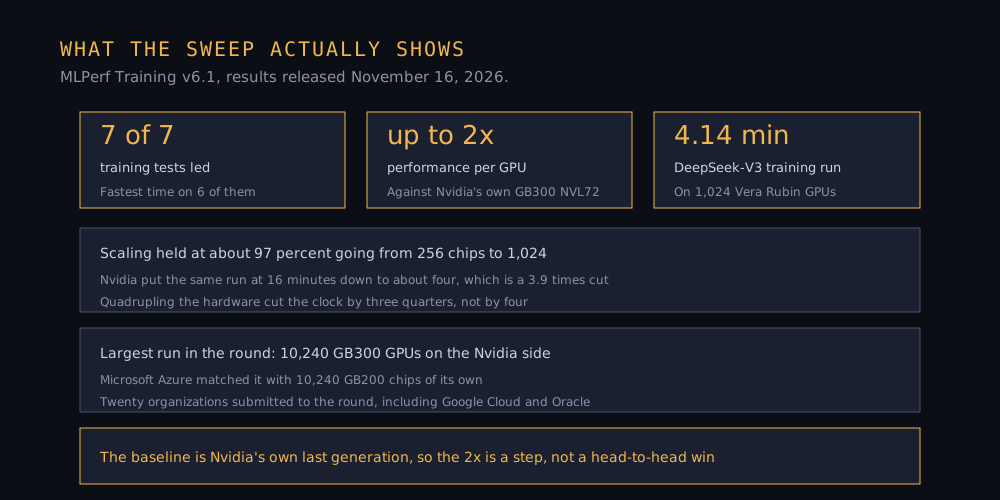
Nvidia was the only vendor with a result on every benchmark in the round. The tests span language models, image generation, recommender systems and post-training. Independent coverage counted seven tests led and the fastest training time on six of them.
"These results are just the beginning," Nvidia said in a post on Monday. Vera Rubin was up to 2x faster per GPU than the GB300 (the older system). The company expects the same machines to post higher numbers as software work continues.
Scaling and power
On the DeepSeek-V3 run, Vera Rubin finished in 4.14 minutes using 1,024 GPUs. Going from 256 to 1,024 chips held about 97 percent efficiency. Nvidia also ran the test on 10,240 GB300 GPUs, the largest scale in the round.
Nvidia frames power as the real limit in a data center. "Because AI data centers are limited by power, the more tokens a system can generate each second for every watt of power, the more agents it can serve and the more value it creates," Nvidia said. Power is what a buyer pays for each month.
Verification gaps
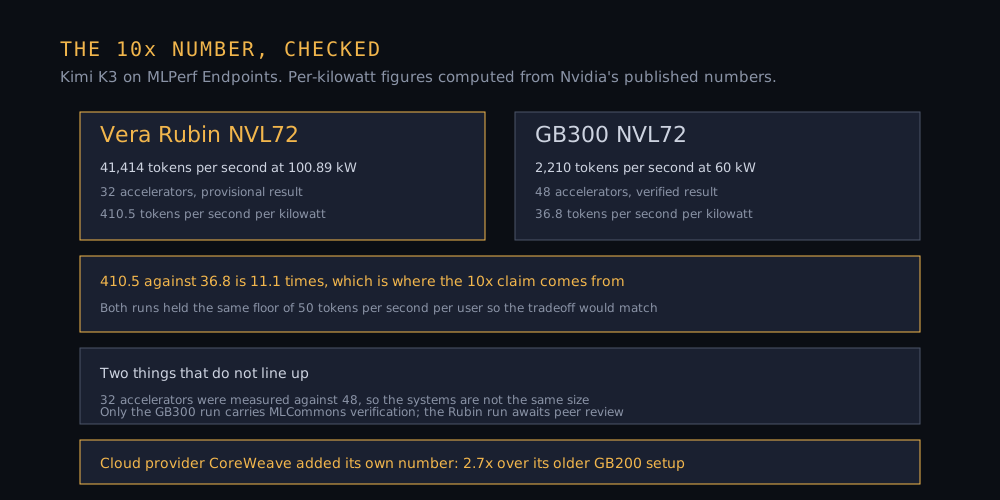
The biggest number in the release carries a caveat. The 10x per watt figure on Kimi K3 is provisional, and MLCommons has not checked it. The GB300 run beside it did pass that check.
The two systems also differ in size: 32 accelerators against 48. Both were held to the same floor of 50 tokens per second per user. CoreWeave said a 256 chip Vera Rubin run beat its previous system by 2.7 times.
Competitor response
Twenty organizations submitted to the round, among them Google Cloud, Oracle and CoreWeave. Azure matched Nvidia's largest run with 10,240 GB200 (its previous generation) chips. The comparison base is Nvidia's own previous system.
The 2x number therefore measures a step rather than a win over a rival. CoreWeave published its own run as an independent data point beside the vendor claims. Nvidia also points at SemiAnalysis and Artificial Analysis numbers that sit outside MLPerf.
Market context
The results land at the supercomputing conference running this week. AI shares are weak this week, with Anthropic's listing expectations slipping on the same days. Buyers setting 2027 capacity contracts are reading these numbers right now.
Sources
← Previous
The United States now needs a license to send AI chips to data centers that serve China
Next →
OpenAI ships GPT-6.2 Astra at $8 per million, matching Anthropic's price eight days later
The Morning Recap
We sift the day. You make the calls.
The decision on every story, in your inbox before your first call.