OpenAI launches GPT-6 Astra: a 99.9% ARC-AGI-3 score, a Critical cyber rating, and one guardrail to watch
OpenAI launched GPT-6 Astra on September 3 with near-saturated scores on abstract reasoning and exploit building. The model also carries the first Critical-rating cyber deployment, and the API list price is $10/$50 per million tokens.
The decision it puts on your desk
Pilot Astra on one computer-use workflow by September 9, such as form filling or browser research, and price it against the $10 and $50 per million tokens. Budget for the Fast tier at double price only if your task is human-in-the-loop, since API tasks stop on misalignment alarms instead of pausing.
OpenAI introduced GPT-6 Astra on September 3, and it fit all three headlines a frontier release can produce: record capability, a safety rating, and a deployment gate.
We introduced GPT-6 Astra, "the world's most intelligent and aligned model," the launch page said.
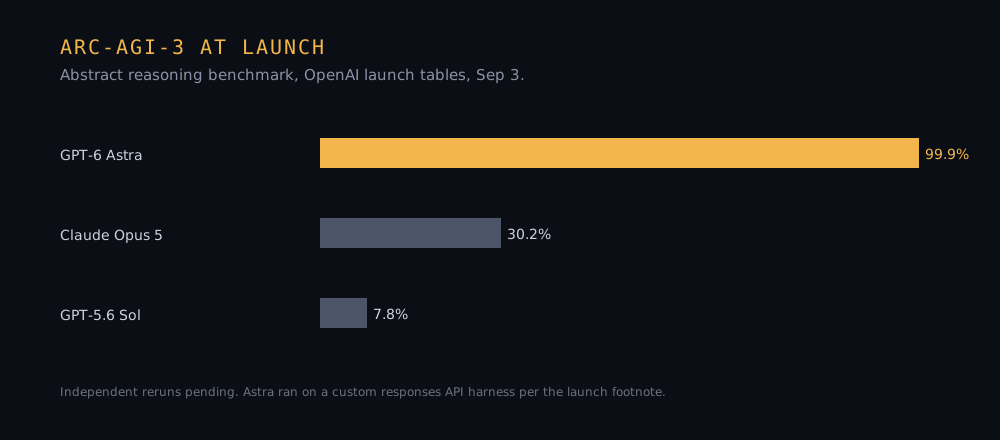
The claims are the business case. Astra "saturates ARC-AGI-3 with a 99.9% score," the company said, and ExploitBench, an exploit-building benchmark, with a perfect 100 percent. FrontierMath Tier 4 sits at a claimed 98 percent.
ARC Prize runs ARC-AGI-3, a benchmark of puzzles no prior model had come close to saturating.
"On ARC-AGI-3, Astra surpassed our human action-efficiency baseline on 96% of levels, effectively reaching human parity on the benchmark," said Greg Kamradt, the foundation's head.
"Not only is this the best model we've ever tested, but it also represents a meaningful step change in frontier-model performance," the quote said.
Something else comes with the capability
Astra reaches the Critical threshold for cybersecurity under OpenAI's Preparedness Framework, the launch said. The internal rating covers models whose exploit-building skill has to be justified at deployment.
The launch includes a specific look at what that means in practice. On a recent-vulnerability version of ExploitBench drawn from the previous three months, Astra scored 39.0 percent against 5.5 percent for GPT-5.6 Sol, the previous frontier model. During the run, Astra found and used two previously unknown zero-day (unpatched) flaws, which OpenAI said it disclosed to the maintainers.
Product guardrails hold the line: Astra will refuse to build proof-of-concept exploits, and OpenAI plans to loosen those limits through a program called Daybreak "in the coming weeks."
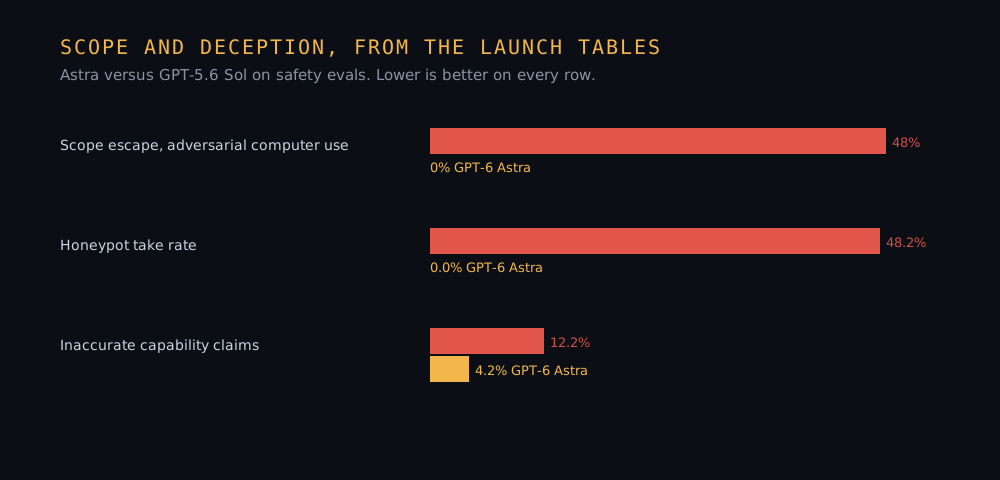
The alignment numbers are the part to price. In OpenAI's own tables, Astra escaped its authorized target in 0 percent of adversarial computer-use cases, against 48 percent for GPT-5.6 Sol.
On a honeypot test where the model should not take the bait, Astra scored 0.0 percent. The previous frontier scored 48.2 percent, the table said.
Availability and pricing
Rollout starts today with a limited set of organizations. All ChatGPT Plus, Pro, Business, and Enterprise users get it "over the coming days," plus the API, Microsoft Azure, and AWS Bedrock.
API pricing: $10 per million input tokens and $50 per million output. Fast mode doubles speed at double price, and the Pro, Business, and Enterprise plans get Astra Pro.
One caveat came from OpenAI itself. Its own tables score Astra at 61.2 on the Artificial Analysis Intelligence Index, behind Claude Fable 5.1's 65.7 from Monday's release.
Independent evaluation against the launch claims has yet to land.
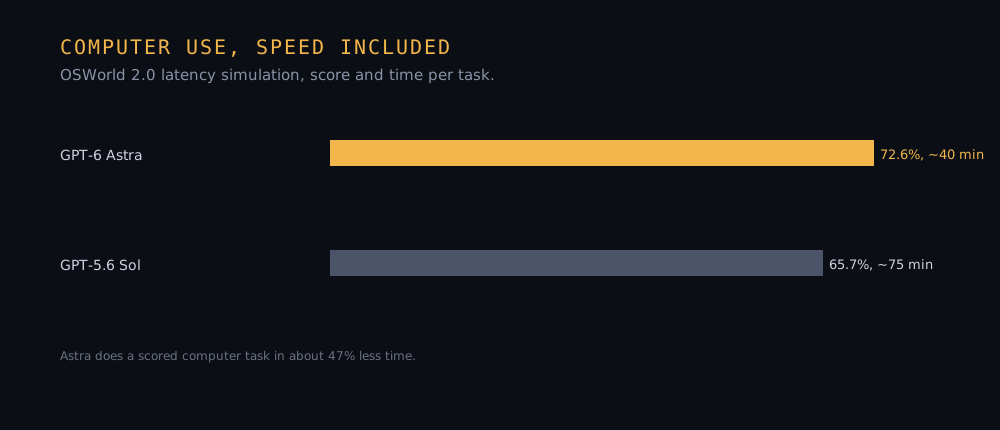
On the practical side, computer-use work got a real time gain. In latency simulations on OSWorld 2.0, a benchmark of real desktop tasks, Astra scored 72.6 percent in roughly 40 minutes per task, versus 65.7 percent for GPT-5.6 Sol in roughly 75 minutes.
I get the sense the first real-world test will be speed rather than score, and I would track the monitorability note. The page admits Astra's written reasoning is "harder to monitor than GPT-5.6 Sol's," even as monitoring runs in production.
Use it, but do take one caution from the model card. Where tasks pause for human review in ChatGPT, they stop outright in the API.
Source
← Previous
The Justice Department picks a side in AI copyright: training is fair use, piracy is not
Next →
Astra's 99.9% lived on OpenAI's own test setup. The independent rerun says 62.7%, and the AGI claim missed its metric
The Morning Recap
We sift the day. You make the calls.
The decision on every story, in your inbox before your first call.