Nvidia ships open Nemotron models that run on one GPU. The chip vendor just attacked cheap-and-cloud from below
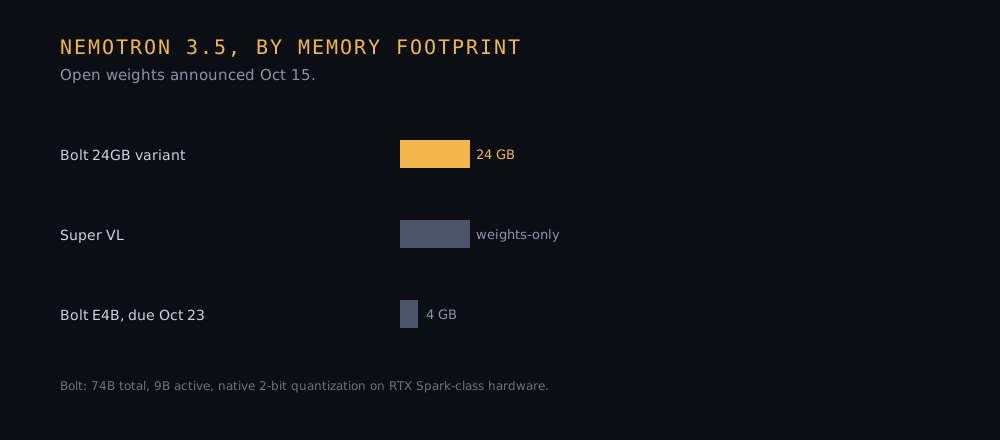
Nvidia released open Nemotron 3.5 models on Wednesday, including a 24GB Bolt variant that runs a 74B-parameter mixture-of-experts model with 2-bit native quantization on consumer-class hardware.
The decision it puts on your desk
Test SaaS agents against a local Nemotron 3.5 Bolt instance on one workload by October 23, when the 4GB variant ships. If the 2-bit quality holds on your workload, add a local tier to your function and route cost-tier agent traffic to hardware you control, while the API bills only the quality-tier calls.
Nvidia's Wednesday release carries a hedge inside a shipping story, and the component worth reading is the memory claim.
Nemotron 3.5 Bolt is a 74 billion parameter mixture-of-experts model, with 9 billion active per token, that fits inside 24 gigabytes of memory through native 2-bit quantization (weights compressed to 2 bits per parameter), landing on RTX Spark-class machines, per the launch materials.
Alongside Bolt, Nvidia released Nemotron 3.5 Super VL, a 120 billion parameter vision-language model, with weights, datasets, and training recipes public.
A 4GB Bolt variant joins the family October 23, the research pages note.
The two opens set the positioning statement: the chip vendor that sells H100 clusters by the thousands also ships open models squeezed onto desktops.
Who the 24GB tier serves
Follow the money from the chip side, since every shipped open model carries a hardware motive.
Agents that run locally cut three costs at once: per-token API spend, latency, and the data exposure that sends work off-site. Each of those carries a business case on its own.
Ecosystem check sits with the cheap-Chinese-model tier. Open-weight competition in the cost tier has been led by Chinese releases all month, so a 24GB desktop model gives Western teams a self-hostable option inside the same tier rather than the frontier exclusively.
Precedent check: Mistral shipped a trillion-parameter open model this month, so weights that run on a small cluster stay the differentiator, not total scale.
The unresolved edge is quality at 2-bit. Vendor quantization is published from one set of runs, and downloaded weights let every benchmark team rewrite the story.
I get the sense the released family is priced for test-and-learn: a fleet of small models on desks that keep the base work inside the building, with Nvidia hardware underneath.
Source
← Previous
Modal raises $750M at $15.75B after crossing $1B in run rate. Serverless GPUs are the layer growing fastest
Next →
Anthropic stopped hiring juniors because its agents outwork them. First-party data on what agents did to an employer
The Morning Recap
We sift the day. You make the calls.
The decision on every story, in your inbox before your first call.